InterEdit: Navigating Text-Guided Multi-Human 3D Motion Editing
Y. Yang, D. Wen, L. Qi,, W. Kong, J. Zheng, R. Liu, Y. Chen, C. Wu, K. Yang, Y. Fu, D. P. Paudel, L. Van Gool, and K. Peng
Published in European Conference on Computer Vision (ECCV), 2026
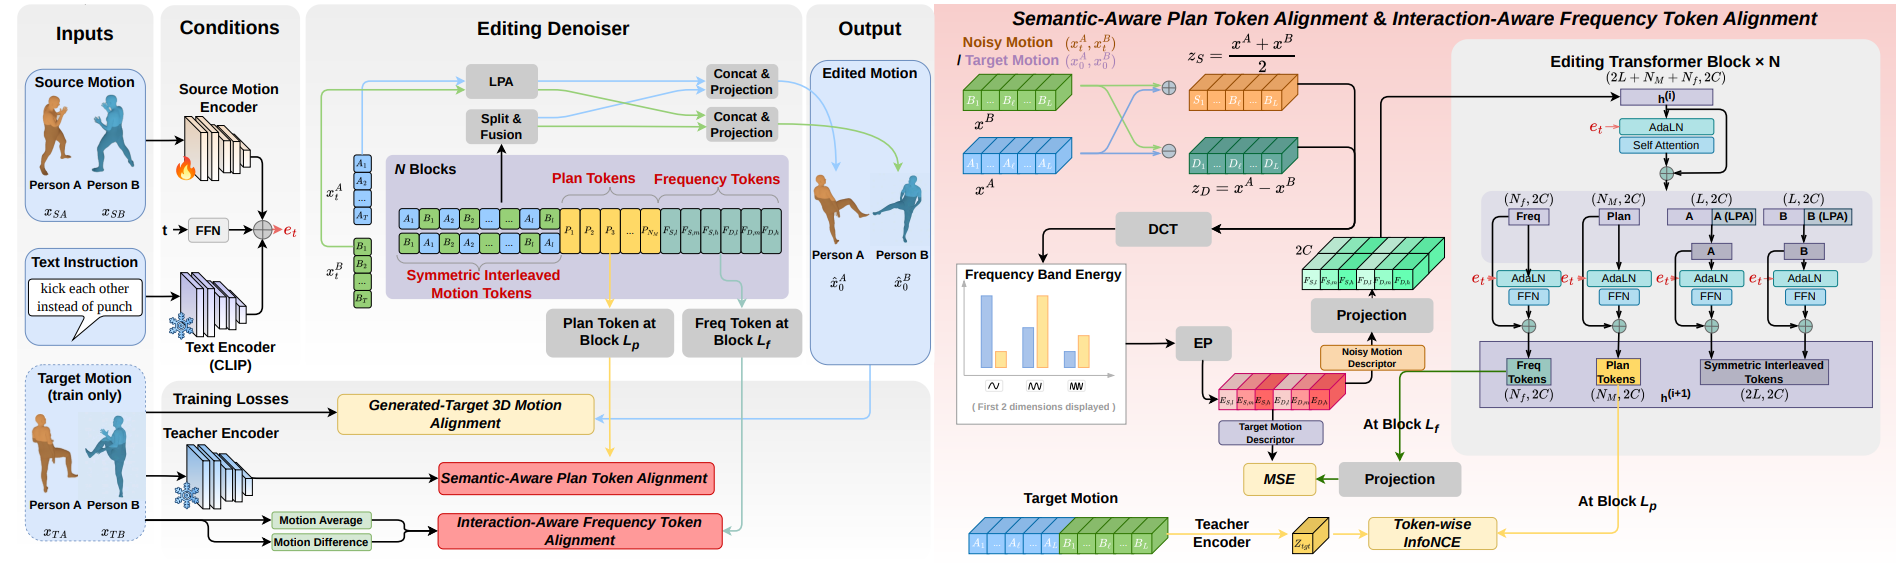
Abstract: Text-guided 3D motion editing has seen success in single-person scenarios, but its extension to multi-person settings is less ex-plored due to limited paired data and the complexity of inter-personinteractions. We introduce the task of multi-person 3D motion editing,where a target motion is generated from a source and a text instruction.To support this, we propose InterEdit3D, a new dataset with man-ual two-person motion change annotations, and a Text-guided Multi-human Motion Editing (TMME) benchmark. We present InterEdit,a synchronized classifier-free conditional diffusion model for TMME. Itintroduces Semantic-Aware Plan Token Alignment with learnable to-kens to capture high-level interaction cues and an Interaction-AwareFrequency Token Alignment strategy using DCT and energy poolingto model periodic motion dynamics. Experiments show that InterEditimproves text-to-motion consistency and edit fidelity, achieving state-of-the-art TMME performance. The dataset and code will be released athttps://github.com/YNG916/InterEdit.
If you are interested in this work, please cite as below:
@inproceedings{yang2026interedit,
  author = {Yang, Yebin and Wen, Di and Qi, Lei and Kong, Weitong and Zheng, Junwei and Liu, Ruiping and Chen, Yufan and Wu, Chengzhi and Yang, Kailun and Fu, Yuqian and Paudel, Danda Pani and Van Gool, Luc and Peng, Kunyu},
  title={InterEdit: Navigating Text-Guided 3D Dyadic Human Motion Editing},
  booktitle={Proceedings of the European Conference on Computer Vision (ECCV)},
  year={2026}
}